Filter by intent
Split training crawlers from bots that fetch pages for live AI answers, and focus on the traffic that counts.
Agent Analytics
Log every AI crawler that reaches your site, read its purpose, and decide which bots deserve access.
Six months of fictional brand trends. Use the metric tabs and focus a month to inspect sample values.
Compare the fictional brands in this sample
| Brand | Visibility | Sentiment | Position |
|---|---|---|---|
| 1Rosebay | 65% | 86 | 2.7 |
| 2Bluehaven | 62% | 62 | 2.9 |
| 3Northwind | 47% | 89 | 3.6 |
| 4Sunfield | 32% | 76 | 3.9 |
| 5Pinegrove | 21% | 88 | 2.3 |
| Domain | Type | Used | Avg. citations |
|---|---|---|---|
| Fforum.example | UGC | 32% | 41% |
| Jjournal.example | Editorial | 43% | 38% |
| Gguide.example | Comparison | 31% | 30% |
| Nnorthwind.example | Corporate | 28% | 24% |
| Aanswers.example | Other | 19% | 17% |
Most cited domains, grouped by type
↗ Fictional brand trends
Split training crawlers from bots that fetch pages for live AI answers, and focus on the traffic that counts.
List the URLs that fail when AI bots request them, then close those gaps.
Kept AI shows how your robots.txt treats each crawler — blocked, allowed or not covered — so you never shut out the bots you actually want.
Follow AI crawl trends per bot, model and URL from one week to the next.
Features
Example data · not customer results
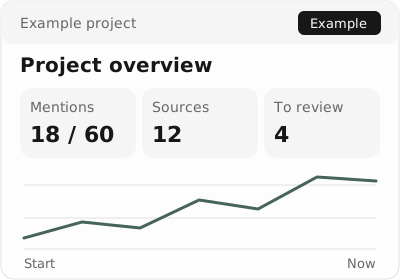
Review crawler categories before interpreting visits as interest from a buyer.
Training: 24 requests · Retrieval: 16
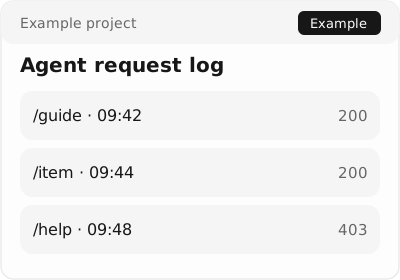
Inspect URL and status-code pairs to choose the next access fix.
/guide → 200 · /old-guide → 404
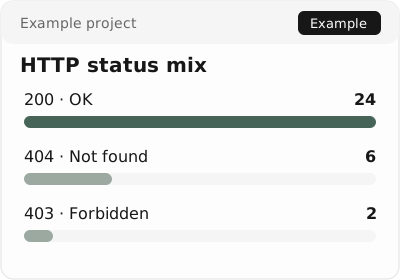
Check robots rules alongside observed requests before changing access policy.
2 paths need a robots.txt review
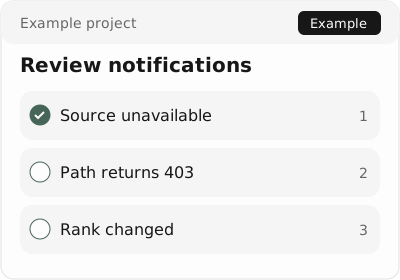
Keep crawler visits and human referrals separate when reviewing outcomes.
40 crawler requests · 3 referral visits
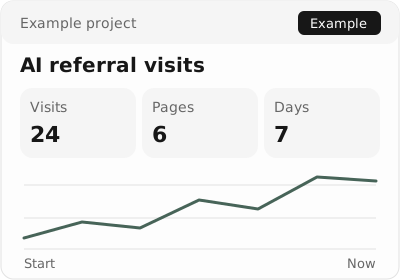
Start with a failed URL or a crawler rule that needs review.
Confirm whether that crawler should access that page.
Review later status codes; access alone does not guarantee a citation.
Use the domain-specific records in your connection flow. Confirm origin and certificate readiness before changing production DNS; a tracked project alone is not a connected gateway.
Prepare the host record and gateway target shown in your connection flow.
Complete domain control validation and check DNS, certificate, and origin status in the app.
After connection, inspect crawler requests and status codes in Agent Analytics.
Example DNS record. Replace the host and follow the target supplied by the app.
www.example.com. CNAME gateway.freem.ai.Integrations
Use the data available in your project. MCP reads results; review any assistant-generated draft before exporting or sharing it.
“I would fix a blocked guide first, then inspect the next crawl before claiming an improvement.”
Agent Analytics is the Kept AI module that monitors the key AI bots visiting your site, including those run by ChatGPT, Gemini, Perplexity and Claude. It reports which bots arrive, which pages they fetch, and whether robots.txt lets them in or keeps them out.
Connect a supported provider such as Cloudflare in a few steps, or upload a raw access log. Once connected, Kept AI starts logging each request AI bots make to your site right away.
Every AI answer begins with a fetch. When bots can't reach a page, or run into errors, that page can't show up in AI results. Watching AI bot requests lets you catch and fix those failures, put effort into the content that matters, and link what bots read to what ends up cited.
Classic search crawlers such as Googlebot index pages for ranked search results. AI crawlers such as GPTBot, Claude-Web and PerplexityBot fetch content so ChatGPT, Claude or Perplexity can answer questions directly. Kept AI groups visits by intent, so you can see whether a page was fetched for model training, for a retrieval index, or live in response to a user's question.
Kept AI recognizes leading AI crawlers for retrieval and training, including those behind ChatGPT, Gemini, Perplexity, Claude, Google AI Overviews, AI Mode and Copilot.
Once you see which AI bots visit, what they fetch and where they are blocked, you can fix errors, tune robots.txt and focus on the pages that feed AI answers. Kept AI links crawler activity to the pages that end up cited.
Yes. Use the MCP server or the API to bring the data into Claude, Cursor and the rest of your stack.